How to Setup DNS
DNS Blog
DNS: What does it mean?
DNS meaning
Domain Name System (DNS) is a naming database system. It is locating and translating domain names into IP addresses. Imagine it is like a directory or even like a mobile’s contacts list. Each one of the names corresponds with numbers, and they are accurately matched. DNS directory is spread worldwide. This system operates daily. It helps to explore and reach millions of domain names every day. Without Domain Name System, we would have to remember each site’s IP address to visit it. This sounds nearly impossible, considering how many sites are out there.
DNS over TLS Explained: How DoT Protects Resolver Traffic
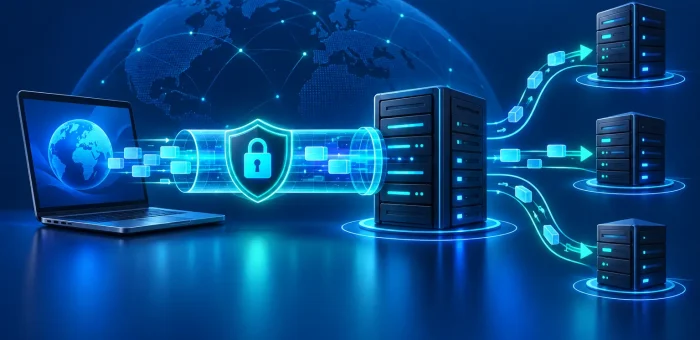
Traditional DNS queries are commonly sent without encryption. Anyone able to observe the path between a device and its recursive resolver may be able to see the names being requested, and an active attacker on that path may try to interfere with the exchange. DNS over TLS, usually shortened to DoT, protects this part of resolution by carrying DNS messages through an encrypted TLS connection.
DoT improves confidentiality and integrity between the client and the selected resolver. It does not hide every network destination, make the user anonymous, or automatically protect communication beyond the resolver. Understanding that boundary is essential when deciding where and how to deploy it.
How DNS over TLS works
A device first establishes a TCP connection to a DoT-capable recursive resolver, conventionally on port 853. It then performs a TLS handshake, validates the resolver’s identity according to the configured authentication policy, and sends ordinary DNS messages inside the encrypted connection.
The DNS questions and answers retain their normal wire format. TLS changes the transport channel rather than the records themselves. Connections can be reused for multiple queries, which avoids repeating the full setup for every lookup and reduces overhead.
The recursive resolver still performs the rest of the lookup process: it uses cached data when available or queries root, top-level-domain, and authoritative servers. The existing article Recursive DNS server explained describes that role in more detail.
DoT compared with traditional DNS
Conventional DNS commonly uses UDP on port 53 and switches to TCP when required. Those transports do not provide encryption or server authentication by themselves. DoT places DNS inside TLS, adding confidentiality, integrity protection, and the ability to authenticate the resolver endpoint.
Encryption prevents a local observer from directly reading the DNS payload between client and resolver. It also makes undetected modification of that protected exchange much harder. However, an observer may still infer activity from destination IP addresses, connection timing, traffic volume, and other metadata.
DoT compared with DNS over HTTPS
DNS over HTTPS, or DoH, also encrypts DNS messages with TLS, but it carries them through HTTPS and normally uses port 443. DoT uses a dedicated DNS-over-TLS service, conventionally on port 853. A practical comparison is available in the ClouDNS guide to DoT and DoH, placed here in the first half of the article.
The dedicated port makes DoT easier for network administrators to identify, permit, redirect, or block. DoH can blend with ordinary HTTPS traffic and is frequently configured inside a browser or application. That can be useful on restrictive networks but may bypass local DNS policy, internal zones, or organization-approved filtering.
Neither protocol is universally superior. A managed network may prefer system-level DoT for clear policy control, while a browser or application may use DoH for portability. The important questions are who selects the resolver, how its identity is authenticated, what happens when encryption fails, and whether all applications follow the same policy.
Privacy and security benefits
Protection on untrusted local networks
On public Wi-Fi or another network you do not control, plaintext DNS can expose query names to nearby or on-path observers. DoT encrypts the DNS exchange from the device to the configured resolver, reducing this local visibility.
Integrity of the client-to-resolver channel
TLS detects modification of protected messages and authenticates the server when certificate verification and resolver naming are configured correctly. This helps prevent a network attacker from silently replacing DNS answers on that segment.
Consistent resolver choice
A device configured with a known DoT resolver can use the same service across multiple networks rather than automatically accepting the DNS server advertised by each local router. This creates a clearer trust relationship, although it also makes the selected resolver an important dependency.
The limits of DNS over TLS
DoT protects only the connection between the client and recursive resolver. The resolver sees the questions it must process and may associate them with connection metadata. Resolver selection therefore matters. Review the operator’s logging, retention, filtering, jurisdiction, security, and availability policies.
Communication from the recursive resolver to authoritative DNS servers is not automatically encrypted merely because the client used DoT. The resolver may use ordinary DNS upstream unless the architecture explicitly supports additional protected transports.
DoT also does not conceal the IP address contacted after resolution, secure an unsafe website, replace HTTPS, block malware by itself, or guarantee anonymity. It is one privacy and transport-security control within a larger system.
DoT and DNSSEC solve different problems
DoT encrypts and authenticates a transport channel to a resolver. DNSSEC allows a validating resolver to verify signatures on DNS data and build a chain of trust from the root. A resolver can use both: DoT protects the client connection, while DNSSEC validation checks the authenticity and integrity of signed records.
The article DNSSEC explained covers that separate security model. Neither mechanism repairs an incorrect record; authenticated incorrect data remains incorrect.
Strict authentication and fallback behavior
Encryption without reliable endpoint authentication may connect the client securely to the wrong resolver. A strong deployment knows the intended resolver identity and validates its certificate. The client should also have a defined policy for connection failure.
A strict policy refuses to send the query in plaintext when the authenticated DoT service is unavailable. This preserves privacy but can interrupt DNS resolution during an outage or blocked connection. An opportunistic policy may fall back to ordinary DNS, improving reachability but allowing a network to force a downgrade and observe queries.
The appropriate choice depends on the environment and risk model. Whichever behavior is chosen should be visible, documented, and monitored rather than silently assumed.
Where DoT can be configured
Operating system
System-level configuration can protect queries from multiple applications and give administrators a consistent policy. Implementation details vary, and applications that use their own resolver libraries may bypass the system setting.
Router or gateway
A local gateway can accept DNS from client devices and forward it to an external resolver over TLS. This protects the gateway-to-resolver segment, but client-to-gateway queries may remain unencrypted unless the local network uses an encrypted mechanism as well.
Local forwarding resolver
A managed forwarding service on the device or network can provide caching, policy, and DoT upstream. Administrators must secure the local listener and ensure that firewall rules do not expose an unintended open resolver.
Testing a DNS over TLS deployment
Begin with ordinary lookups to establish expected answers. The site’s DNS lookup guide explains common tools, but note that a standard dig query does not prove the operating system used DoT.
Verify the deployment at several layers:
- Confirm resolver identity. Check the configured endpoint name and successful certificate validation.
- Verify the transport. Use client logs, resolver logs, packet capture, or platform diagnostics to confirm TLS on the expected connection.
- Test normal records. Resolve A, AAAA, MX, and other types used by applications.
- Test DNSSEC behavior. Confirm that valid signed domains resolve and known validation failures are handled as expected.
- Test failure policy. Block or stop the DoT endpoint temporarily in a controlled environment and observe whether the client fails closed or falls back.
- Check internal names. Ensure corporate, VPN, split-horizon, and local-service names continue to resolve under the selected policy.
- Measure performance. Compare connection setup, reused-connection latency, cache behavior, and failure recovery.
Operational considerations
Port 853 must be reachable through relevant firewalls and captive networks. The resolver needs valid certificates, capacity for TLS connections, connection reuse, monitoring, and protection against resource exhaustion. Clients need accurate time for certificate validation and a trusted certificate store.
High availability is important because an enforced encrypted resolver becomes a critical dependency. Configure supported backup endpoints carefully and make sure failover does not silently select a resolver with a different privacy or filtering policy.
The protocol requirements and message framing for DNS over TLS are defined in RFC 7858: Specification for DNS over Transport Layer Security.
Conclusion
DNS over TLS protects DNS messages between a client and recursive resolver with an authenticated encrypted connection. Its dedicated transport is well suited to system and network policy, but the privacy benefit depends on correct certificate validation, a trustworthy resolver, explicit fallback behavior, and reliable operations. Use DoT alongside HTTPS, DNSSEC validation, secure endpoints, and clear monitoring rather than treating it as a complete privacy solution.
How to Set Up DMARC: Policy, Alignment, and a Safe Rollout
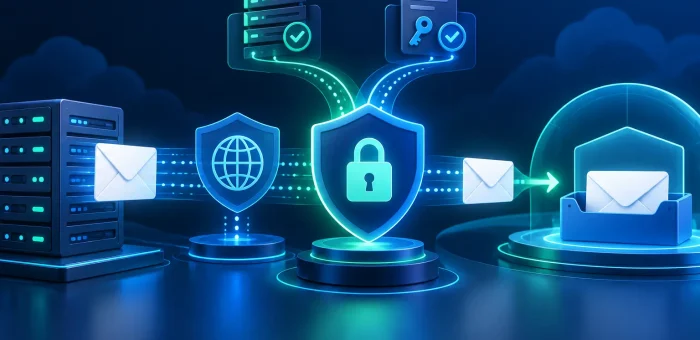
A domain can have working email and still be vulnerable to impersonation. Attackers may place its name in the visible From address, hoping recipients will trust a message that did not come from an approved system. DMARC gives domain owners a way to connect SPF and DKIM authentication to that visible identity, request reports, and tell participating receivers how to handle messages that fail.
A safe DMARC setup is a process rather than a single aggressive DNS change. The reliable approach is to inventory every legitimate sender, make SPF or DKIM align correctly, begin with a monitoring policy, study the reports, fix gaps, and then move gradually toward quarantine or rejection.
What DMARC does
DMARC stands for Domain-based Message Authentication, Reporting, and Conformance. A receiving mail system evaluates SPF and DKIM results, checks whether the authenticated domain aligns with the domain shown in the message’s From header, and applies the published DMARC policy.
A message can pass DMARC when at least one of these paths succeeds:
- SPF passes and its authenticated MailFrom domain aligns with the visible From domain.
- DKIM passes and the domain in a valid DKIM signature aligns with the visible From domain.
Requiring alignment is important. SPF alone authenticates the envelope sender used during delivery, which may differ from the address a person sees. DKIM authenticates the signing domain, which also may be different. DMARC connects a successful authentication result to the visible identity. For a broader overview of the mechanism and its anti-phishing purpose, see this guide to DMARC.
Prepare SPF and DKIM first
Confirm every legitimate sending source
Create an inventory of systems that send mail using the domain: primary mail providers, marketing platforms, support desks, transaction services, billing tools, monitoring systems, website forms, and any service that sends on behalf of a subdomain. An incomplete inventory is the most common reason legitimate mail begins failing when enforcement increases.
Check SPF authorization and alignment
SPF lists which systems may send for an envelope domain. Make sure each legitimate source is covered without creating multiple SPF records or exceeding the protocol’s DNS-lookup limits. The existing article on how the SPF record works explains the authorization side in more detail.
For DMARC, an SPF pass is useful only when the authenticated MailFrom domain aligns with the visible From domain. Under relaxed alignment, the domains may share the same organizational domain. Strict alignment requires an exact match. A third-party platform may therefore pass its own SPF check but still fail the SPF path for your DMARC policy unless it supports a custom aligned return-path domain.
Enable DKIM signing with an aligned domain
DKIM adds a cryptographic signature to the message. The receiver retrieves the public key from DNS and verifies that signed parts of the message were not altered. Review the DKIM record guide if you need a refresher on selectors and public keys.
For DMARC alignment, the domain in the DKIM signature’s d= value must align with the visible From domain. Many email platforms support custom DKIM signing for this reason. DKIM often survives forwarding better than SPF, although mailing-list modifications can invalidate a signature if they change signed content.
Create the DMARC TXT record
Publish DMARC as a TXT record at _dmarc.example.com, replacing example.com with the domain used in the visible From address. A sensible monitoring record can look like this:
v=DMARC1; p=none; rua=mailto:dmarc-reports@example.com; pct=100The essential tags are straightforward:
- v=DMARC1 identifies the protocol version and must appear first.
- p=none requests monitoring without asking receivers to quarantine or reject failures.
- rua provides one or more addresses for aggregate reports.
- pct specifies the percentage of applicable messages subject to the requested policy; 100 is the default.
Use a real, monitored mailbox or a suitable report-processing service for aggregate reports. Reports are typically XML files and may arrive in volume. Confirm that the receiving mailbox can handle the traffic and treat report data according to the organization’s privacy and retention requirements.
Understand policy and alignment options
Policy levels
- p=none: Request reporting and normal receiver handling. Use it to discover legitimate senders and authentication gaps.
- p=quarantine: Ask receivers to treat failing messages as suspicious, often by placing them in spam or applying extra scrutiny.
- p=reject: Ask receivers to reject messages that fail DMARC evaluation.
These are requested policies, and final message handling remains with the receiver. Moving directly to p=reject can block legitimate traffic if a forgotten service lacks alignment.
Relaxed and strict alignment
The aspf and adkim tags control SPF and DKIM alignment. Relaxed mode, represented by r, is the default and permits aligned subdomains within the same organizational domain. Strict mode, represented by s, requires the domains to match exactly. Strict alignment is not inherently necessary for every domain; use it only when sending architecture and policy require the tighter match.
Subdomain policy
The sp tag can define a separate requested policy for subdomains. Before setting it, identify subdomains that send mail and those used only for websites or services. A domain that should never send mail can often use stronger controls, but verify that no operational tool depends on it first.
Read aggregate reports before enforcing
Aggregate reports summarize how participating receivers see mail claiming to use the domain. They commonly show source IP addresses, message counts, SPF and DKIM results, alignment outcomes, and the policy applied. They do not automatically tell you whether a source is legitimate; administrators must map sources to known services and investigate unfamiliar traffic.
Use the monitoring period to answer practical questions:
- Which approved platforms send mail for the domain?
- Does each source pass aligned SPF, aligned DKIM, or both?
- Are forwarding and mailing-list flows producing expected failures?
- Do unknown sources indicate spoofing, stale systems, or an incomplete inventory?
- Are high-volume failures concentrated in one provider or subdomain?
Move to enforcement gradually
- Start with p=none. Collect enough representative reports to cover normal campaigns, billing cycles, and infrequent systems.
- Fix legitimate senders. Configure aligned DKIM or a custom return path, remove obsolete sources, and correct DNS records.
- Test quarantine. Move to
p=quarantineafter known sources pass consistently. Continue checking reports and support feedback. - Increase coverage deliberately. If using
pctduring rollout, increase it only after reviewing the affected traffic and understanding receiver behavior. - Adopt reject when ready. Use
p=rejectwhen legitimate sources are aligned, exceptions are documented, and monitoring is ongoing.
DMARC does not replace correct mail routing. MX records still identify where inbound mail should be delivered, while DMARC evaluates messages that claim to come from a domain. The article MX record: Why is it important? explains that separate role.
Verify and maintain the deployment
After publishing the TXT record, query the exact _dmarc name from multiple resolvers and confirm that only one syntactically valid DMARC record is returned. Send controlled tests through every approved platform, inspect authentication results in message headers, and verify that aggregate reports begin arriving.
Continue reviewing reports after enforcement. Vendors, sending IPs, return-path domains, and DKIM selectors change over time. Add DMARC review to the onboarding and removal process for every email service, protect access to DNS and mail-provider accounts, and rotate DKIM keys according to provider capabilities and policy.
The protocol’s discovery, alignment, policy, and reporting model is defined in RFC 7489: Domain-based Message Authentication, Reporting, and Conformance.
Conclusion
A successful DMARC setup begins with visibility. Inventory legitimate senders, establish aligned SPF or DKIM, publish a monitoring record, analyze aggregate reports, and correct failures before enforcement. Gradual movement from none to quarantine and then reject protects legitimate mail while making domain impersonation harder and giving administrators useful feedback about abuse.
Anycast DNS Explained: Faster and More Resilient Resolution
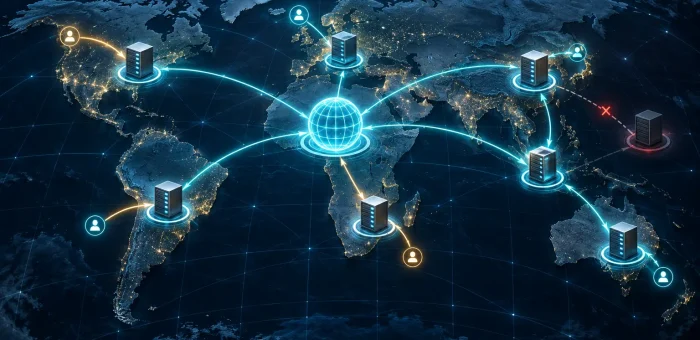
DNS has to answer users wherever they are, often before a website, application, or email service can do anything useful. If every query must travel to one distant server, network delay and a single infrastructure failure can affect the experience. Anycast DNS addresses this challenge by allowing multiple distributed servers to provide a service through the same IP address.
Routing systems direct each query toward an available location based on the network’s current path selection. The result can be lower latency, wider capacity, and better resilience than a service operating from only one location. The idea sounds simple, but a reliable deployment depends on coordinated routing, synchronized DNS data, health checks, and careful operations.
What is Anycast DNS?
In an Anycast design, DNS servers in multiple locations advertise the same service IP address. Internet routing—normally using the Border Gateway Protocol, or BGP—selects a path toward one of those locations. A user in one region may reach one server, while a user elsewhere reaches another, even though both send their DNS queries to the same IP address.
The selected node is commonly described as the “nearest,” but that means nearest according to routing policy and topology, not necessarily the shortest geographic distance. Peering relationships, route preferences, congestion, and network changes can all influence the path.
Anycast can be used for authoritative DNS, recursive DNS, content delivery, and other widely distributed services. For background on the different role of a resolver, see Recursive DNS server explained.
How an Anycast DNS query is routed
- A client or recursive resolver sends a DNS query to the service’s published IP address.
- Routers evaluate the available BGP paths for that address.
- The query follows the preferred path to one of the Anycast locations.
- The selected DNS server returns an answer using the same service address.
The application does not need to choose a city or maintain a list of server addresses. Routing makes that decision. If an operator withdraws the route for an unhealthy location, subsequent traffic can move toward another location that still advertises the address.
Why Anycast works well for DNS
DNS transactions are usually short. A query is sent, an answer returns, and the exchange ends quickly. That pattern fits Anycast better than a long-lived stateful session that could be disrupted by a route change halfway through the connection.
Modern DNS also uses TCP in several situations, including larger responses, retries, zone operations, and encrypted DNS transports. Providers therefore have to design their network and server state carefully rather than assuming that every request is a single stateless UDP packet.
Main benefits of Anycast DNS
Lower network latency
Queries can reach a well-connected regional node instead of crossing the Internet to a single origin. A shorter or better network path can reduce round-trip time, especially for a service with a broad user base.
Resilience against a location failure
When a node or network location becomes unavailable, its route can be withdrawn so traffic moves to another site. This avoids depending on one data center, but only when health detection and route control work correctly.
Distributed query capacity
Traffic is spread across multiple locations rather than concentrated on one server cluster. This provides more aggregate capacity and can help absorb regional traffic spikes.
A smaller attack concentration
Distributed nodes can prevent all malicious traffic from converging on one location. However, Anycast is not automatically complete DDoS protection. Capacity, filtering, rate controls, upstream cooperation, and incident response remain essential.
Anycast DNS and traditional redundancy
Anycast and secondary DNS solve related but different problems. Anycast makes one service address reachable from several routing locations. Secondary DNS gives a zone additional authoritative servers that can answer independently and receive zone data from a primary system.
A strong architecture can use both. For example, each authoritative provider may operate its own Anycast network, while the domain delegates to independent nameserver sets. The concepts in Backup DNS: Everything you need to know help explain why logical provider redundancy still matters.
What Anycast DNS does not guarantee
- It does not guarantee the geographically closest server. BGP selects routes according to network policy and reachability.
- It does not fix incorrect zone data. Every node can quickly return the same wrong answer if the underlying configuration is wrong.
- It does not replace DNSSEC. Anycast improves distribution and reachability; DNSSEC authenticates DNS data.
- It does not remove the need for monitoring. Operators must observe routing, node health, answer consistency, latency, and capacity.
- It does not eliminate every outage. Shared software, control-plane, configuration, or provider failures can affect multiple nodes at once.
Operational requirements behind a reliable service
Consistent DNS data
Every active node must serve the intended zone version. Providers need dependable distribution, validation, and rollback procedures so a partial update does not create different answers in different regions.
Accurate health checks
A server can be reachable while returning incorrect answers. Health checks should test the DNS service itself and validate important responses, not only confirm that a machine responds to a network probe.
Controlled route withdrawal
Failover depends on detecting a real problem and withdrawing the affected route without causing unnecessary instability. Operators should test this process and understand how quickly routing changes are accepted by neighboring networks.
Capacity in every failure scenario
The remaining nodes must handle redirected traffic when one or more sites are unavailable. Normal average load is not enough for capacity planning.
Global monitoring
Testing from multiple networks helps reveal regional routing problems that a monitor near the provider may not see. Useful measurements include DNS response correctness, latency, packet loss, route visibility, and the location serving each probe.
How to evaluate an Anycast DNS provider
When comparing services, look beyond the number of advertised locations. Ask how those locations connect to other networks, how traffic is shifted during failure, and how the provider verifies consistent answers. The existing list of DNS hosting providers provides a starting point, while the following questions help with deeper evaluation:
- Where are the active Anycast points of presence, and how are they connected?
- Does the provider publish uptime and incident information?
- How are unhealthy routes withdrawn, and are DNS answers tested before withdrawal?
- Are DNSSEC, access controls, change logs, monitoring, and DDoS defenses available?
- Can the service handle traffic when several locations fail simultaneously?
- Is independent secondary DNS supported for provider-level diversity?
Conclusion
Anycast DNS uses routing to make the same service address available from multiple network locations. It can reduce latency, distribute query load, and allow traffic to move away from an unhealthy site. Those benefits depend on sound BGP operations, synchronized zone data, application-level health checks, sufficient spare capacity, and monitoring from many regions.
For another practical overview, see What is Anycast DNS and how does it work?. The operational behavior and design considerations for Anycast services are documented in RFC 4786: Operation of Anycast Services.
Get familiar with Dynamic DNS
Description of Dynamic DNS
First off, Dynamic DNS, also known as DDNS, is a service that will instantly update your IP address (the A or AAAA record) if the host (device) changes it.
When your IP address’s lease ends, your ISP (Internet service provider) can change it automatically.
You can use DDNS to ensure that the device will remain accessible if you utilize it as a server. Otherwise, you won’t be able to reach the new IP address or determine it from a distance.
Without Dynamic DNS, if you are operating a monitoring server with a camera at home and you have been viewing the video from a distance, the connection will break the instant the ISP changes the IP address, and you won’t be able to see anything.
Backup DNS: Everything you need to know
So, do you want to be 100% sure that your domain is online? Backup DNS for your Primary DNS service is a handy addition that will make your DNS network broader. If you use a Backup DNS, you can add multiple nameservers that will be authoritative for your domain and answer queries.
What is a Backup DNS service?
Backup DNS service (Secondary DNS) is an additional DNS service that you can get from another DNS provider, different from your primary, with the goal to add extra redundancy. You can use extra nameservers as authoritative, and they can answer queries too.
DNS zone – What do you need to know about it?
DNS zone – What does it mean?
The DNS is made up of numerous DNS zones. Moreover, the DNS server you’re using can better handle several zones to manage the DNS namespace. So, we can say that a DNS zone is a subset of the DNS namespace that a single administrator manages. It’s utilized as an organizational segment to provide you more control over DNS things like authoritative namespaces.
For your domain to function correctly, you must point it to various servers, including web servers, mail servers, etc. This is accomplished by adding multiple types of DNS records to the DNS zone. So, the DNS zone is where all Domain Name System records are stored. It is also the lone component responsible for the existence of the Domain Name System (DNS).
How does the SPF record work?
SPF record – definition
The Sender Policy Framework record, or simply for short SPF record, is a DNS record that indicates the email servers that are qualified for sending email messages on behalf of the domain name.
Cyber-criminals are capable of forging emails in a lot of different ways. So, they are able to change the “Mail from” and mask the emails to look like legit ones coming from a particular domain. Yet, they actually are not from the original source.
Thanks to the SPF record, it is possible to establish strict rules. The DNS administrator applies SPF to precisely limit who is able to use the domain to send emails. The recipient, on the other hand, is able to check the authorization.
PTR record: Why is it important?
What does the PTR record mean?
The PTR record, also known as a pointer record, has a very precise goal. It has to point the IP address to the domain name. In addition, this type of DNS record is able to work either with IPv4 addresses or with IPv6 addresses efficiently. Therefore, thanks to the pointer record, you are able to configure and perform Reverse DNS.
This DNS record gives the ability to ensure and verify that the particular IP address is exactly belonging to the domain name. That is very important when it comes to sending an email. The receiving mail servers usually desire to verify the source of the email and perform a reverse DNS lookup. Therefore, they examine and seek exactly the PTR records.
Recursive DNS server explained.
The Recursive DNS server has a significant role in the Domain Name System. So, let’s explain a little bit more about it.
What is the purpose of DNS?
The Domain Name System, or for short DNS, is a fundamental piece of the Internet. It includes a process in which the different domain names are translated into their corresponding IP addresses (IPv4 or IPv6). There are two different ways to request a domain. The first way is also the human way by using the domain names. That is an alternative for humans to memorize only the name of their requested and preferred website. The second way is also the machine way by using the IP address. They use the long series of numbers to communicate with other machines and computers successfully.
MX record: Why is it important?
MX record is one of the common DNS records that is essential to know. Each action that you want to perform and is related to domains also requires DNS records for guidance. So let’s explain what the purpose of it is and why it is important.
MX record explained
You can probably find the MX record to be called a mail exchanger record. Don’t get confused. It is the same thing. The DNS MX record points to which server is arranged for accepting the emails that go for an exact domain.
For example, if you want to send an email to Daniel@example.com, your device will have to know the location of Daniel’s email host. Therefore, it will view for the MX record on the name server of the domain. This server has the data for the domain example.com. After once you have it, your device will get the information about the server, which is arranged to accept the mail. After that, it will send the email there.
So to get it clear.
People need it to send you emails. More accurately to your domain. They receive the information about where the mails are supposed to be sent and the correct server.